Crusoe Managed Inference
Inference
that scales
Serve models with ultra-low latency and high throughput. Now with flexible deployment options that fit your workload.
Trusted by:



Crusoe's inference engine is powered by MemoryAlloy™ technology, a unique cluster-native memory fabric that persists across nodes and enables intelligent routing to eliminate redundant prefill computation.
Flexible deployment options
Model hub
Explore a curated selection of pre-configured top open models from leading AI labs, ranging from lightweight and ultra-fast to large with frontier reasoning power.

This is some text inside of a div block.
models
Model
Parameters
Context
AVAILABLE FOR
Qwen3 235B A22B Instruct
Parameters
235000000000
Context
262144
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/qwen.png
Alibaba
Qwen3.5 9B
Parameters
9000000000
Context
262144
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/qwen.png
Alibaba
Qwen3.6 27B
Parameters
27000000000
Context
262144
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/qwen.png
Alibaba
Qwen3.5 2B
Parameters
2000000000
Context
262144
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/qwen.png
Alibaba
Qwen3.5 35B A3B
Parameters
35000000000
Context
262144
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/qwen.png
Alibaba
GLM-5.2
Parameters
753000000000
Context
262144
AVAILABLE FOR
Self-Serve Deployments
https://cdn.prod.website-files.com/6855c1aa175582ee23e0aa19/6ad7f87e8869856dbfafb3ca_zai-padded.png
Z.ai
Gemma 4 26B A4B
Parameters
25200000000
Context
262144
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/gemma.png
Google
Qwen3 8B
Parameters
8200000000
Context
40960
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/qwen.png
Alibaba
Qwen3.6 35B A3B
Parameters
35000000000
Context
262144
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/qwen.png
Alibaba
Llama 3.3 70B Instruct
Parameters
70000000000
Context
131072
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/meta.png
Meta
GPT-OSS 20B
Parameters
21000000000
Context
131072
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/openai.png
OpenAI
Nemotron 3.5 Super VL 120B A12B
Parameters
120000000000
Context
262144
AVAILABLE FOR
Serverless Inference
https://cdn.prod.website-files.com/6863cc86499b79ce3ab28f8b/69e2d226da896c3332f907b3_m48-nim-256px-grn%20(1)%204.png
NVIDIA
GLM-5.3 Flash
Parameters
321000000000
Context
1048576
AVAILABLE FOR
Serverless Inference, Self-Serve Deployments
https://cdn.prod.website-files.com/6855c1aa175582ee23e0aa19/6ad7f87e8869856dbfafb3ca_zai-padded.png
Z.ai
GLM-5.3
Parameters
753000000000
Context
1048576
AVAILABLE FOR
Serverless Inference, Self-Serve Deployments
https://cdn.prod.website-files.com/6855c1aa175582ee23e0aa19/6ad7f87e8869856dbfafb3ca_zai-padded.png
Z.ai
DeepSeek V4.1 Flash
Parameters
552000000000
Context
1048576
AVAILABLE FOR
Serverless Inference
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/deepseek.png
DeepSeek
DeepSeek V4 Flash 0731
Parameters
284000000000
Context
1048576
AVAILABLE FOR
Serverless Inference, Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/deepseek.png
DeepSeek
DeepSeek V4 Pro
Parameters
1600000000000
Context
1048576
AVAILABLE FOR
Serverless Inference
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/deepseek.png
DeepSeek
Gemma 4 31B
Parameters
30700000000
Context
262144
AVAILABLE FOR
Serverless Inference, Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/gemma.png
Google
GPT-OSS 120B
Parameters
117000000000
Context
131072
AVAILABLE FOR
Serverless Inference, Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/openai.png
OpenAI
Llama 3.1 8B Instruct
Parameters
8000000000
Context
131072
AVAILABLE FOR
Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/meta.png
Meta
Nemotron 3.5 Lightning 30B A3B
Parameters
30000000000
Context
262144
AVAILABLE FOR
Serverless Inference, Self-Serve Deployments
https://cdn.prod.website-files.com/6863cc86499b79ce3ab28f8b/69e2d226da896c3332f907b3_m48-nim-256px-grn%20(1)%204.png
NVIDIA
Nemotron 3 Nano 30B
Parameters
30000000000
Context
262144
AVAILABLE FOR
Serverless Inference
https://cdn.prod.website-files.com/6863cc86499b79ce3ab28f8b/69e2d226da896c3332f907b3_m48-nim-256px-grn%20(1)%204.png
NVIDIA
Nemotron 3 Nano Omni
Parameters
31000000000
Context
262144
AVAILABLE FOR
Serverless Inference
https://cdn.prod.website-files.com/6863cc86499b79ce3ab28f8b/69e2d226da896c3332f907b3_m48-nim-256px-grn%20(1)%204.png
NVIDIA
Nemotron 3 Super 120B
Parameters
120000000000
Context
262144
AVAILABLE FOR
Serverless Inference
https://cdn.prod.website-files.com/6863cc86499b79ce3ab28f8b/69e2d226da896c3332f907b3_m48-nim-256px-grn%20(1)%204.png
NVIDIA
Nemotron 3 VoiceChat
Parameters
11000000000
AVAILABLE FOR
Serverless Inference
https://cdn.prod.website-files.com/6863cc86499b79ce3ab28f8b/69e2d226da896c3332f907b3_m48-nim-256px-grn%20(1)%204.png
NVIDIA
Qwen3.8 27B
Parameters
27000000000
Context
262144
AVAILABLE FOR
Serverless Inference, Self-Serve Deployments
https://unpkg.com/@lobehub/icons-static-png@1.97.1/dark/qwen.png
Alibaba
Unmatched performance, flexibility, and scalability
*
Benchmarked against vLLM for Llama-3.3-70B model. Read our blog to learn more details.
In voice, inference latency is the product; users hear every millisecond you didn't optimize. Crusoe tuned our stack against real production traffic, and the payoff is conversation that flows at human speed.

Our biggest fear was that cutting costs would cut the product quality. With Crusoe Managed Inference, performance and latency improved, and we're paying an order of magnitude less.
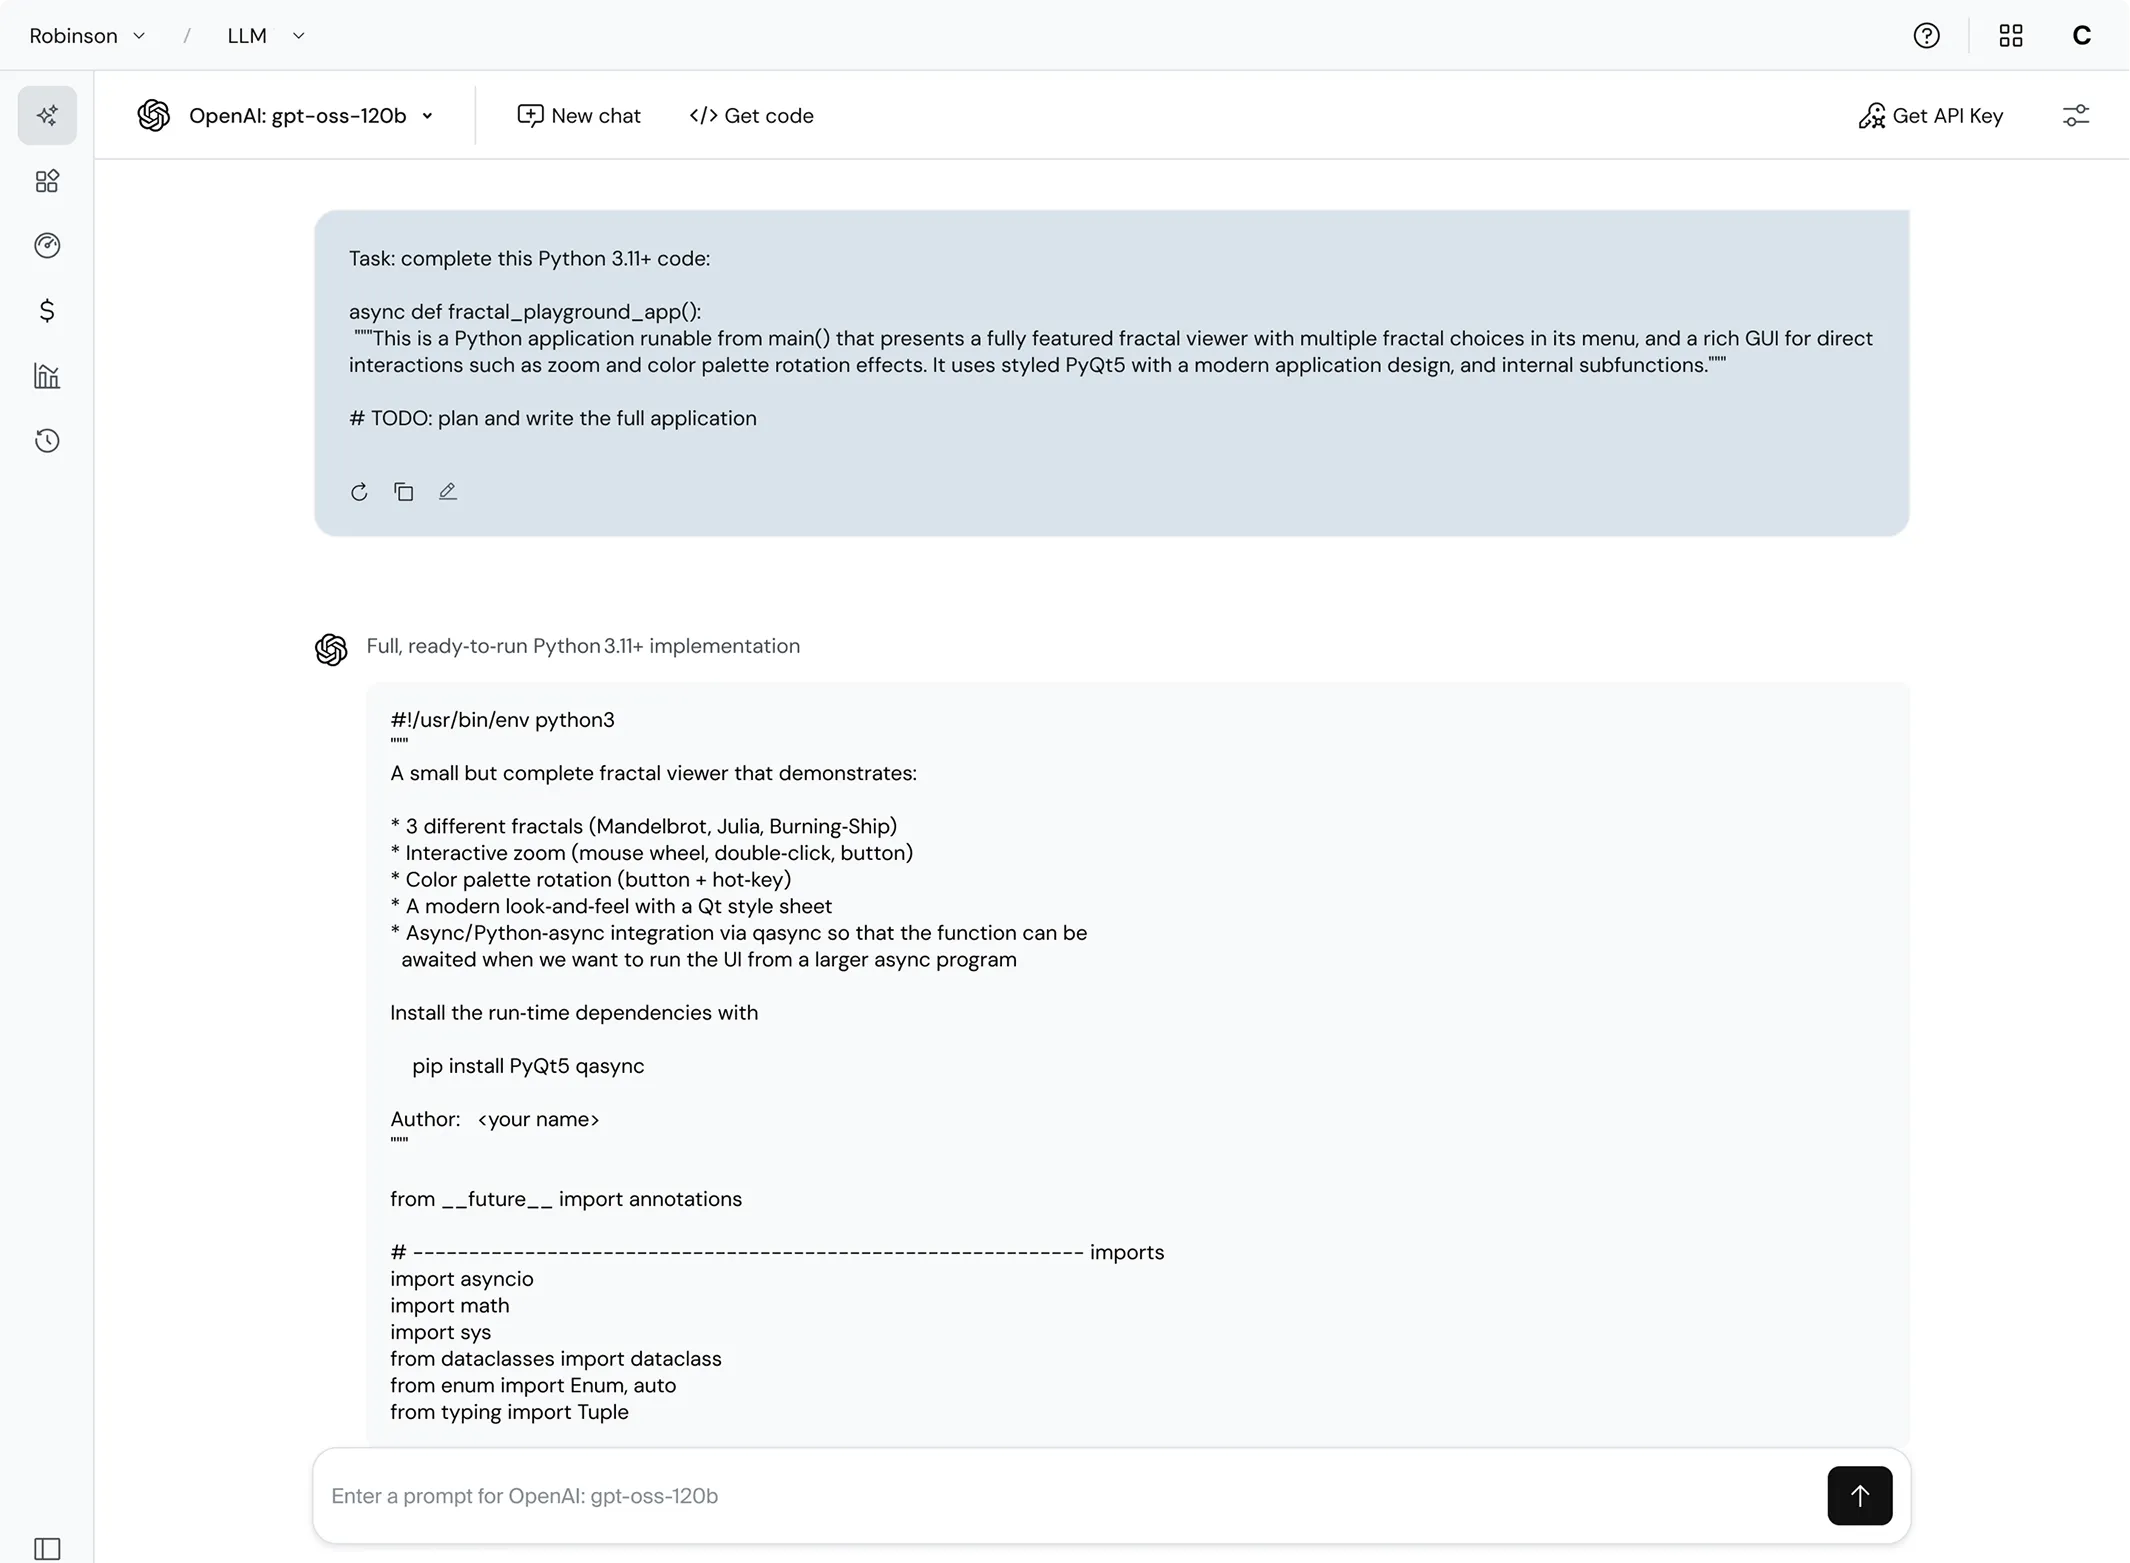
Crusoe Intelligence Foundry, designed for AI developers
Discover new models, accelerate fine-tuning, and quickly deploy with flexible inference options.
Crusoe inference engine vs vLLM
0
2
4
6
8
10
TTFT
Throughput
x Improvement vs. vLLM
Llama-3.3-70B model, 4-node deployment
Frequently
asked questions
Can I run inference on my own model?
What if I want a dedicated instance?
What optimization profiles are available, and how do I choose?
What models are available for Managed Inference?