Ollama scales open models with Crusoe Managed Inference on Crusoe Spark modular data centers
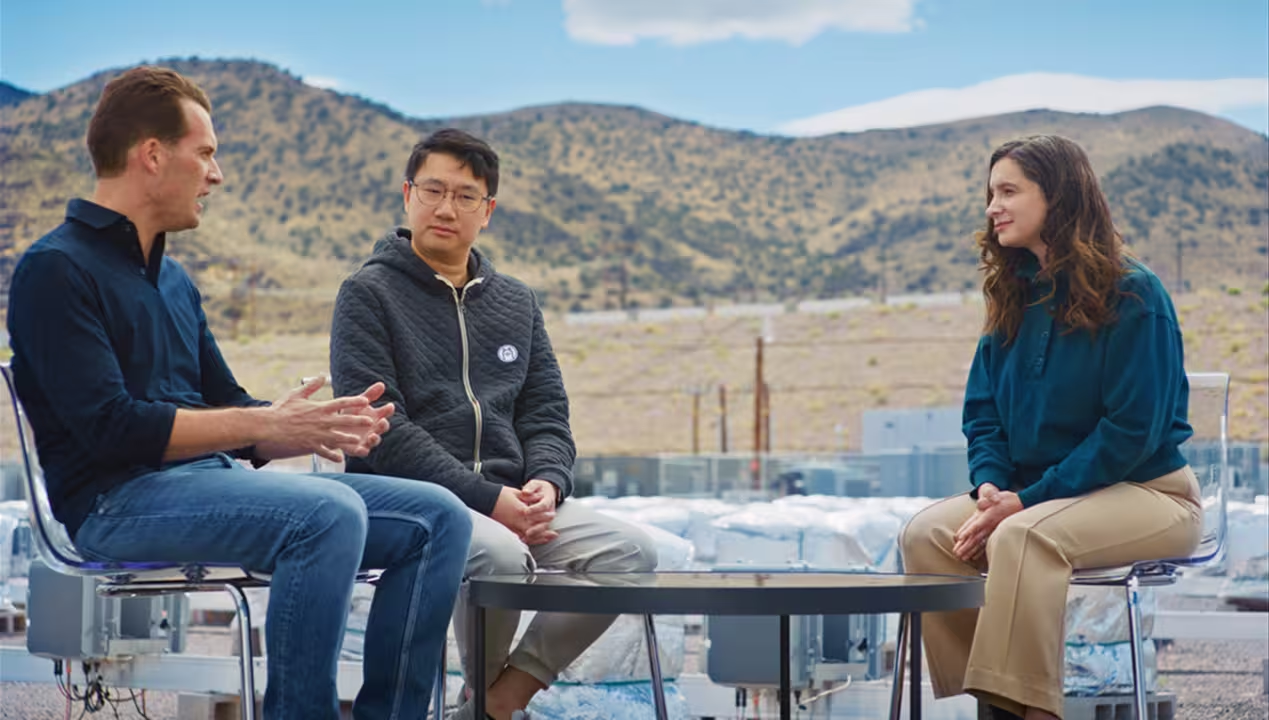

It’s the location of the data in Crusoe Spark close to these developers, along with Crusoe Managed Inference, that allows us to have the performance to be the top-performing open-source platform. And that's the critical need of our developers.
Bringing local AI models to the cloud
Ollama started as a local tool built on the ethos of "Your model. Your machine. Your data.” Co-founders Jeff Morgan and Michael Chiang created a platform where developers could run AI models entirely on their own hardware with full ownership of their data.
The combination took off. Since January 2026, Ollama’s token volume has grown 200x. More than 9 million developers now use the platform, and 85% of Fortune 500 enterprise teams are represented in its user base. Workflows span everything from agentic coding, co-work agents, to enterprise applications across regulated industries including pharmaceuticals, finance, and legal.
That growth plus the growth of frontier open models created a scaling challenge. "Not everybody has the best local computers that can run the larger models for their everyday tasks," Chiang explains. "And this is when we introduced Ollama’s cloud, where we run the best frontier open models." Choosing the right inference provider became mission critical.
The challenge: Privacy, volume, and shifting traffic
Ollama's users range from individual developers running personal coding agents to Fortune 500 security teams with strict compliance requirements. Serving both populations on the same platform at 200x growth demanded three things from an infrastructure partner.
- Verifiable data residency: Enterprise security teams need complete visibility into where compute runs and where data lives. "We care a lot about data privacy," Michael Chiang, Co-founder, stresses, "So it's important for us to pick a provider that allows us to see where our customers’ data is going."
- Dynamic compute flexibility: End users demand adaptable capacity across shifting traffic shapes to avoid rigid serverless vendor lock-in. “On any given day we have some of the largest token consumption with open-source models globally,” observes Michael Meltzer, Chief Business Officer at Ollama, “And the traffic shapes change hour to hour.” The underlying capacity has to absorb burst spikes without degrading latency for the rest of the user base.
- Active co-engineering collaboration: Developer teams need deeply integrated technical support to fine-tune serving infrastructure directly around real-world workloads. Rather than renting cold, unoptimized API endpoints from commodity cloud providers, Ollama required a hands-on engineering team capable of optimizing performance at every layer.
"Reliability and performance are the most important aspects," Chiang says. "And we're able to deliver that with Crusoe."
The solution: Vertical integration from modular solar infrastructure to inference
Ollama chose Crusoe to deploy an end-to-end stack spanning physical site infrastructure through managed model serving. "Crusoe provides that vertical stack where we can serve the developers for their tasks end-to-end," Chiang explains, "and that creates the performance, the data privacy that's necessary, and the latency that's required to serve them at scale."
Crusoe Spark modular data centers in Nevada
The compute foundation sits in Nevada, running on Crusoe Spark modular data center units manufactured in Colorado. Instead of waiting years for traditional builds, these units ship on the back of flatbed trucks and install directly onto concrete pads. The facility operates on above 99% solar power with on-site battery storage, giving Ollama’s enterprise customers the data provenance they require: workloads run on U.S. soil.
"When we first heard from the team about Crusoe Spark units, we said, 'This is perfect to scale with our needs,'" Meltzer recalls.
Crusoe Managed Inference: NVIDIA Accelerated Computing Infrastructure tuned for open models
Inside the Crusoe Spark modular data centers units, Ollama runs on NVIDIA Blackwell systems through Crusoe Managed Inference, which handles the orchestration that absorbs Ollama’s volatile traffic while maintaining low latency across the full model catalog. NVIDIA Blackwell systems feature groundbreaking advancements, including the second-generation Transformer Engine enabling NVFP4 and fifth-generation NVIDIA NVLink scale-up, delivering unprecedented performance, efficiency, and scale for generative AI and accelerated computing.
"Ollama serving all these models on NVIDIA Blackwell GPUs, and performance is paramount for developers who are just getting started," Chiang notes. "Having the latest technology means a lot to them."
Engineering partnership: Around-the-clock co-optimization
The serving layer works because the engineering relationship behind it is continuous. The Ollama and Crusoe teams operate jointly, tuning model deployments against live traffic around the clock.
"When we built the relationship with Crusoe, it all starts with people," Meltzer says. "We want to work with the best and brightest engineering minds, which helps build the trust that this is top-tier, reliable, managed inference." In practice, that means the two teams work together on the engineering side to make sure models are tuned to what Ollama's developers need.
The impact: Speed, scale, and day-zero delivery
Ollama saw results quickly. Within two weeks of closing the deal, the team had production compute running in Nevada. Ollama's developers were using the capacity before most traditional data center deployments would have finished procurement.
That speed is critical because new open models ship constantly, and Ollama's users expect access on day one. "We strive to be a day-zero partner and to have the models quickly available to all the developers," Meltzer says. "These models are coming fast and furiously. And Crusoe has been instrumental in making sure that these models can scale with our users, and that's included some of the largest models that have come out." Behind that velocity is continuous operational work between the two teams. "We will be speaking with the Crusoe Managed Inference team at all hours of the night, whether it be East Coast time or in Tel Aviv," Meltzer adds.
Crusoe Managed Inference also handles the throughput and latency demands that come with Ollama serving billions of tokens per day across a global user base. The serving layer dynamically routes traffic across the GPU fleet so that response times stay low even as token volume spikes, giving Ollama's developers the fast, consistent experience they expect from the platform.
For Ollama's regulated enterprise customers, the deployment in Nevada answers the provenance question that started the provider search. Their data stays on U.S. soil, which is what brought Ollama to Crusoe in the first place.
The same infrastructure handles the full range of Ollama's user base without requiring separate capacity pools. An individual developer running a coding assistant and an enterprise team generating a traffic spike both draw from the same Managed Inference deployment, and the system scales to meet whichever demand shows up. "Having a relationship where we together operate from the power source down to the end user, we believe is a huge piece of being able to offer the best experience to the developers," Meltzer says.
As Meltzer summarizes, "It’s the location of the data in Crusoe Spark units close to these developers, along with Crusoe Managed Inference, that allows us to have the performance to be the top-performing open-source platform. And that's the critical need of our developers."
Looking forward
Ollama’s rapid growth requires infrastructure that can expand at the same pace. The vertically integrated stack built with Crusoe provides the long-term operational blueprint for that scale. "This is the template that's here that's going to scale out with Crusoe to plan for Ollama's future growth," says Chiang.
Deploying additional Crusoe Spark modular data centers —modular data centers that are manufactured off-site rather than constructed on-site—alongside more NVIDIA Blackwell silicon and continued co-engineering allows Ollama to replicate its deployment speed across new regions and upcoming model generations, all with the power of Crusoe Managed Inference. "Crusoe has become a trusted partner because of our dynamic needs. And the growth is not slowing down,” adds Meltzer, “We look forward to building out more of these Crusoe Spark units together."
For developers who started running local weights on personal machines, this cloud expansion creates a direct bridge to enterprise-scale compute, backed by solar-powered modular data centers, verifiable U.S. data residency, and day-zero access to newly released open models.
Explore Crusoe Managed Inference and Crusoe Spark modular data centers
Learn more about Ollama


Related stories
Fireworks went from deal to thousands of nodes running in days on Crusoe Cloud
Fireworks tripled daily token volume to more than 40 trillion in a year. Its co-founder and infrastructure lead explain why Crusoe earns its place in a multicloud strategy: managed Kubernetes, automated node health, and thousands of new nodes over a weekend.
Ready to build on Crusoe?
Talk to our team about your workload.